DeepSeek ships V4.1 Flash with vision, then reverses V4 Pro deprecation
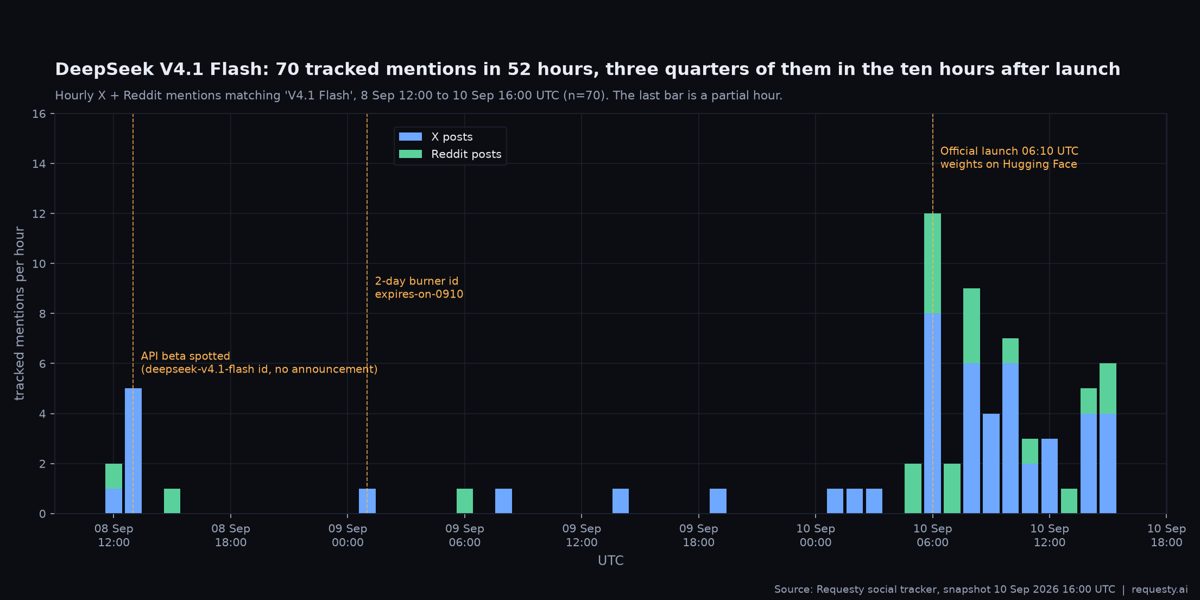
V4.1 Flash is DeepSeek's cost-and-latency-optimized entry, now with native multimodal visual understanding and faster inference. At $0.15/$0.60 per million input/output tokens off-peak, it undercuts frontier rivals dramatically — independent testers on Reddit claimed roughly 98% of GPT-6 Astra's capability at about 1.4% of the cost (~$18 per billion tokens), plus a 10.4-point jump on a CVE-detection benchmark. (Note: sources disagree on scale, with one report citing a 763B-parameter version — DeepSeek's exact parameter count is unconfirmed.)
The more interesting story is the reversal. DeepSeek had announced that starting September 14, all deepseek-v4-pro requests would reroute to V4.1 Flash at Flash rates, effectively retiring V4 Pro. After user pushback, it walked that back, continuing V4 Pro API service with unchanged billing — a rare instance of a lab reversing a deprecation on community demand.
Reception was mixed on r/DeepSeek: enthusiasm for cost-performance ('Today's usage 4.1 flash,' 161 upvotes) sat alongside complaints ('Why are people so satisfied? For me it's such a mess,' 182 upvotes) and a thread calling it 'officially unusable for deep psychological/abstract work' over refusal behavior. The pattern is classic DeepSeek: aggressive pricing and rapid iteration winning cost-conscious developers, while power users debate whether capability keeps pace.