VIDRAFT's 180B Darwin model tops open-weight math and science reasoning, beating a 2.8T-parameter rival
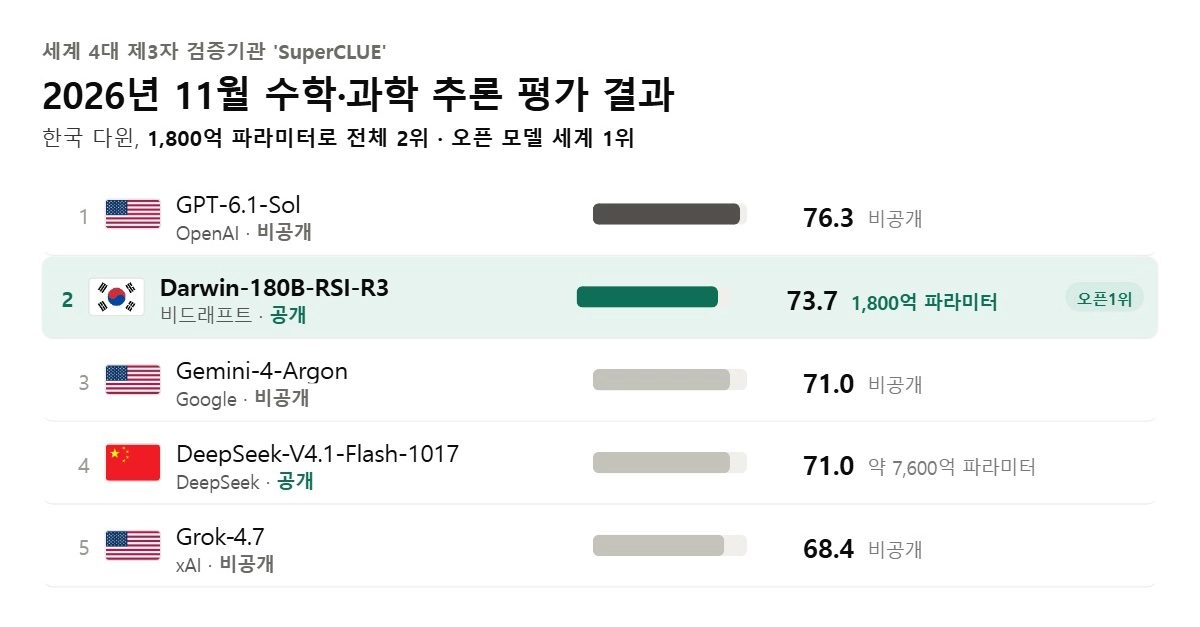
A 180B-parameter model beating one more than 15 times its size on a reasoning track adds to this month's efficiency theme. Qwen4-Max also cut its active parameters, and Mistral Large 4 activates just 52B of its 1T parameters.
SuperCLUE is a Chinese-led benchmark suite. Its math and science reasoning track measures multi-step problem solving rather than general chat quality. The 'RSI' suffix suggests VIDRAFT used a recursive self-improvement-style post-training loop, though the report gives few methodological details.
There are important caveats. This is a single track on a single leaderboard, reported through a dev.to repost of ZDNet Korea coverage. Specialized reasoning wins often do not transfer to coding or agentic tasks, and benchmark contamination is a constant risk. Kimi K3.1 Pro remains far more general.
Still, it is a meaningful signal for Korea's AI scene and for open-weight developers who need strong reasoning at a size that fits on a few GPUs. Watch for independent replication, a technical report, and results on Artificial Analysis or LMArena.