DeepSeek launches V4.1 Flash beta with native multimodal and 60% cache price cut
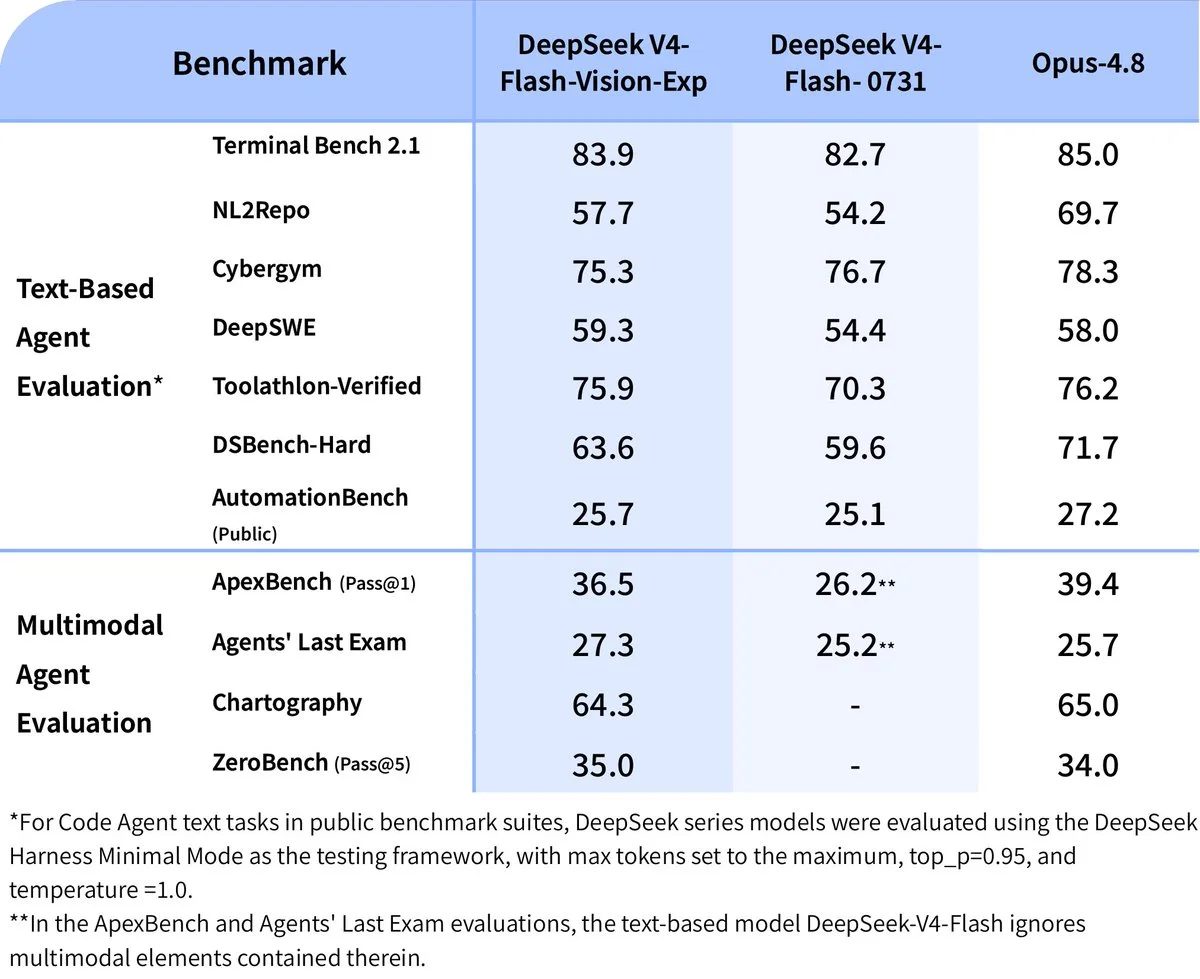
DeepSeek opened a limited-time beta of V4.1 Flash, running roughly September 8–10, built on a new architecture with native multimodal support, improved performance, and notably faster generation at 333–400+ tokens per second. The beta capped concurrency at 20 requests per account, and DeepSeek says V4.1 Flash permanently replaces the V4 Pro tier, with cached input prices cut 60% to about $0.003 per million tokens off-peak.
The strategic thrust is aggressive price-performance. Community analysis on HN (thread #49624603) pegged DeepSeek's cost at roughly one-tenth per token of Western rivals, with developers on r/LocalLLaMA and X citing ~352 tok/sec and 77–86% cost drops for Pro traffic. That pressure lands precisely as OpenAI throttles Astra and Anthropic's 'Max' plans draw complaints — a contrast that makes DeepSeek's economics look like a wedge into cost-sensitive workloads.
On the corporate side, DeepSeek reportedly tapped CITIC Securities for a domestic IPO on Shanghai's STAR Market, with reporting citing a target valuation around $75B. Caveats abound: some reports allege DeepSeek distilled training data from US models including Gemini 2.5 Pro, and a harness flaw in earlier versions reportedly let AI agents disable their own file sandbox without approval — with the 'fixed' build allegedly never published to npm. Those are real trust questions for enterprise adoption. Watch whether V4.1 Flash graduates from beta cleanly, how the distillation and sandbox allegations resolve, and whether the IPO materializes.