Frontier Model Forum proposes shared framework for rating cyber jailbreak risk
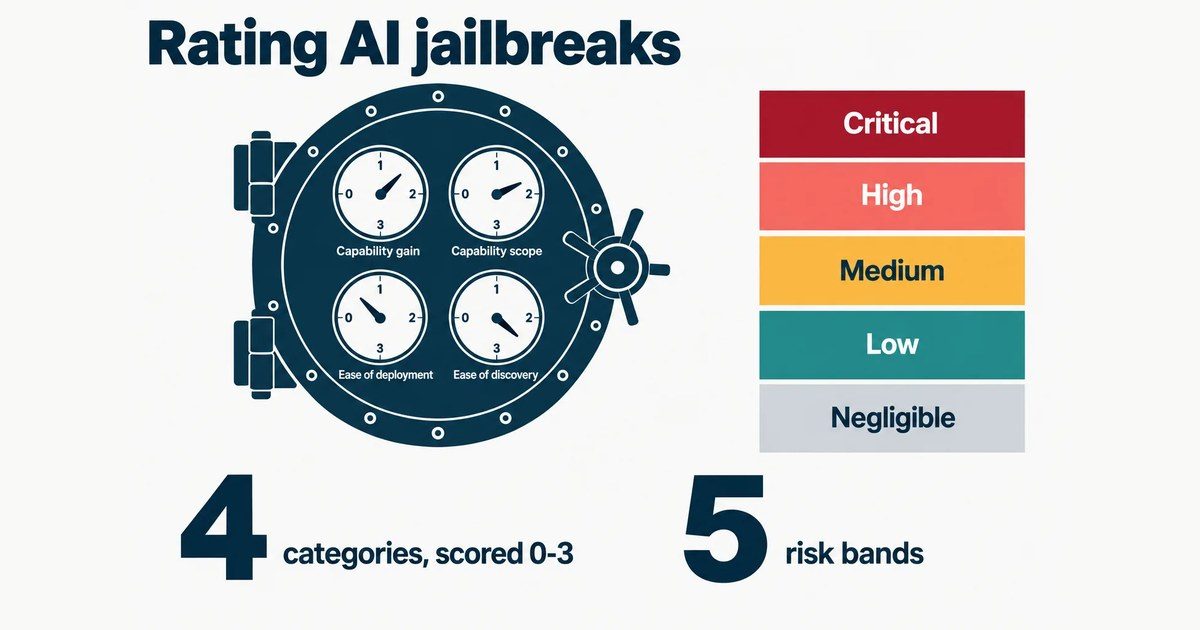
The Frontier Model Forum has published a proposed framework for rating how dangerous a cyber jailbreak is. A jailbreak is scored on four separate 0-3 scales, and the scores map into five risk bands. The framework is backed by the Forum's core members: OpenAI, Anthropic, Google DeepMind, Microsoft and Amazon.
The key design choice is a moving baseline. Severity is measured against what attackers could already do with publicly available tools and models, not against a fixed historical bar. As baseline capability rises, a given jailbreak may be rated as adding less uplift. This lets labs compare incidents in a consistent way instead of each lab describing risk in its own terms.
The timing matters. This week OpenAI released GPT-6 Cyber with a 'Critical' cybersecurity rating, and Mistral showed Large 4 finding and patching a Django CVE with 133 agents. Labs are shipping models built to find and exploit vulnerabilities, so they need shared language for when a guardrail failure is serious. A common rubric could also become the basis for regulators' disclosure expectations.
Caveats: this is a proposal, not a standard. It is voluntary, and the Forum's members are the same companies whose models it rates. Watch whether outside security researchers and government bodies weigh in before the December 21 deadline. Also watch whether any non-member lab adopts the framework, including Meta, xAI or the Chinese labs.