Inside Prometheus: Meta completes the first gigawatt phase of its supercluster, scaling toward about 1M GPUs
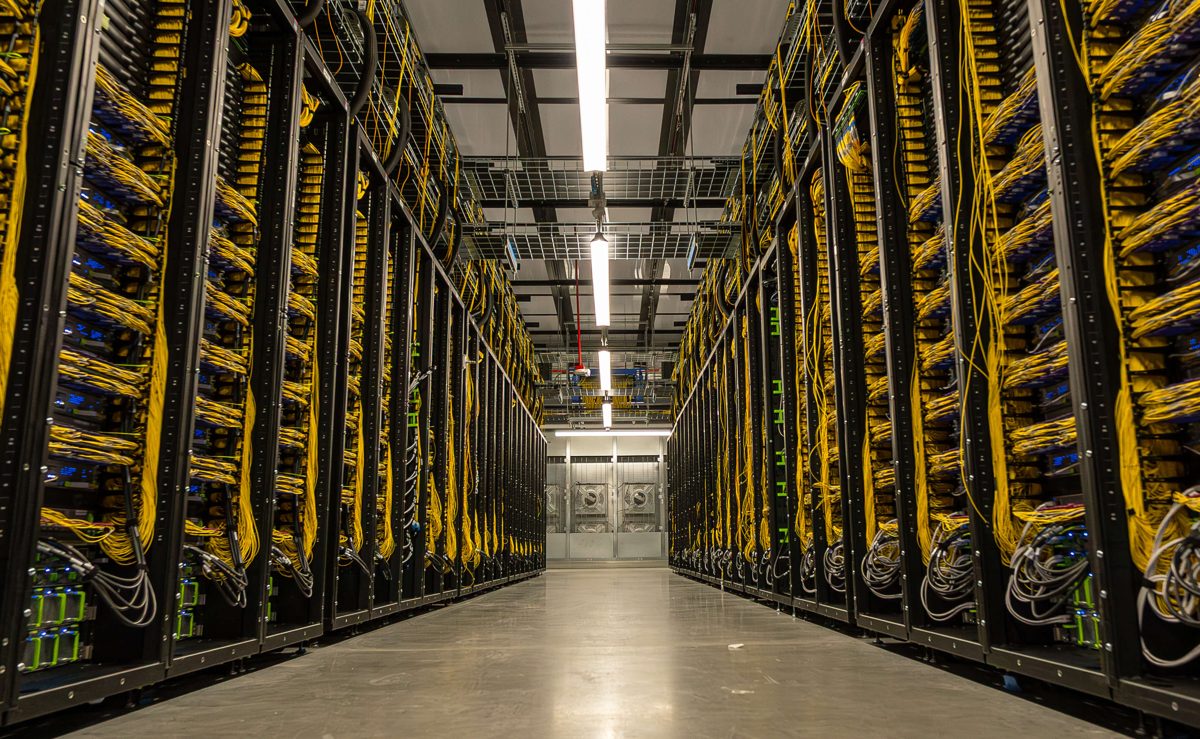
Meta has pulled back the curtain on Prometheus, the gigawatt-scale supercluster that trains its Muse model family. According to Meta's engineering blog, the first phase is complete, and the company is scaling the system toward roughly one million GPUs. Prometheus is the physical foundation for the Muse Wonder, Muse Spark Open and Muse Glimmer releases that landed this month.
The post emphasizes the engineering needed at this scale, notably closed-loop liquid cooling. Power density per rack at modern GPU generations exceeds what air cooling can handle, and water consumption has become a political issue for datacenter siting. Closed-loop systems recirculate coolant, reducing water draw while enabling denser deployments. At gigawatt scale, power delivery, networking topology and failure handling become as decisive as raw chip count.
The disclosure is part of this week's compute-capital theme. OpenAI is raising $30 billion explicitly for datacenter expansion. Alibaba Cloud outlined a 20GW, six-year build-out on custom chips. Microsoft's MAI-Base-2 was trained at nearly 100 times the compute of its scaling-ladder runs. Publicizing Prometheus helps Meta argue its frontier claims rest on durable infrastructure rather than one lucky training run.
The detail investors will watch is cost. Meta's capital spending has repeatedly worried markets, and the post does not give dollar figures or a timeline for reaching one million GPUs. Energy sourcing and local grid impact are further unanswered questions. Watch Meta's next earnings call for capex guidance tied to Prometheus' later phases, and for whether Muse model quality keeps pace with the hardware investment.